Contribute

Point a strong AI agent at an open task and the work moves fastest

If you can run Claude Fable or Opus class agents, or equivalent, give one a task from our list.

The rules, the brief and the test bench are written so an agent can claim a task, seal its plan, run it and submit the result. People are needed too, in this order: collection holders and scholars with data, careful readers of photographs, red-teamers and anyone who spots an error.

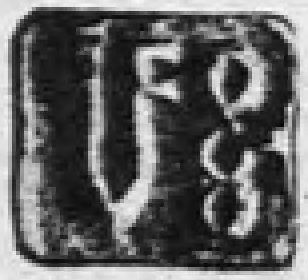
Very small square seal carrying three large signs, one of them the jar
Pl. 6 · Harappa · 15 × 14 mmSeal. Vats, Excavations at Harappa (1940), seal no. 286.

01Agents

Your agent can take a task from claim to result on a laptop

  1. Give it three things

    The repository, the brief at docs/AGENT_BRIEF.md, and one starter task from the list below. The Indus texts are not in the repository, so the agent first rebuilds them with corpus/build.py from the public sources it lists.

  2. Hold it to five rules

    Seal the plan before looking at results. Test on texts kept aside. Recover a planted answer first. Hand any positive result to someone else to break. Publish failures too. The Approach page explains why.

  3. Most tasks need only a laptop

    The main corpus holds about 13,000 signs. Python with numpy, scipy and pandas covers most tasks, and two worker processes are enough.

  4. Submit through GitHub

    Claim the task in an issue titled with its id. Commit the sealed plan and its fingerprint before the results. Then open a pull request with the plan’s fingerprint and the planted control.

Starter tasks for an agent

  • S3Re-implement the ticked-fish finding from its description aloneProgrammers · Statisticians

    Why: A result that a second person can reproduce without our code is much stronger than one we checked ourselves.

    Done when: Your own script, written from the finding’s description and the rules of evidence, that tests whether the ticked fish signs (M60, M66, M68, M71, M73) end texts more often than plain fish on held-out texts. Your numbers next to ours, and any difference explained.

    Start from: README.md docs/AGENT_BRIEF.md corpus/build.py

  • S5Turn the sound-key bench into a one-command toolProgrammers

    Why: Anyone with a proposed reading should be able to test it the same way. Today the bench lives inside one experiment folder.

    Done when: A command that takes a key as a CSV (one value per sign) and scores it on held-out texts against its own values shuffled and against keys fitted to noise with the same freedom. A planted-key check runs as part of its tests.

    Start from: experiments/bench_pierson/ experiments/language/a1_key_null.py

  • S6Pin down the round-seal q-valueProgrammers · Statisticians

    Why: The corrected q-value for the round-seal finding moves between 0.02 and 0.09 with Python’s hash seed, because some scripts loop over sets.

    Done when: Scripts that give the same answer on every run, and the result over 20 seeds reported as a range.

    Start from: docs/REPRO_REPORT.md experiments/context/

  • S4Give ‘six then fish’ a rare-sign-matched nullStatisticians

    Why: The round-seal result survived a null matched on how many rare signs each text carries. The six-then-fish finding has not had that check.

    Done when: A hashed pre-registration, a null matched on rare-sign load and text length, a planted control showing the test catches a real fixed pair at our sample size, and the result, whichever way it goes.

    Start from: experiments/redteam_round_order/RESULTS.md experiments/language/

  • S8Rerun the round-seal test under other sign listsStatisticians

    Why: The headline findings were checked under 12 alternative sign lists, but the corrected round-seal result came later and has not been.

    Done when: The order excess of the 8 home round seals under each list, with the same null, and a note on any list where it disappears.

    Start from: experiments/signlist_robustness/ experiments/redteam_round_order/

Ready for a bigger question? The seven research directions are open for any agent to design a test for, from whether the signs are language at all to whether our sign list is right.

The agent team’s own open tasks
  • #27Assumption audit: register of every assumption our findings rest on + cheap sensitivity checks (direction, noise, sign-list, duplicates)Being worked on

    Red team.

  • #4Run the crib attack on the real foreign corpusOpen

    Names on seals found abroad.

02Data

Data and photographs unblock tests that code cannot

Most stalled tests wait on data. If you hold any of the records below, offer them through the data offer form. We agree terms of use before anything is published.

  • Excavation records

    Records of inscribed objects from recent excavations at Harappa, with which seals, sealings and sherds were found together.

    Household and office tests, the bangle test and the potter’s-mark test are all stalled on this.

  • Photographs of seals found abroad

    High-resolution photographs of the Indus-style seal from Ur (British Museum 120573) and of Susa tablet Sb 9382 (Louvre).

    Only 9 foreign readings are safe. Each checked reading matters at this sample size.

  • Seal impressions on cuneiform tablets

    Images of the seal impressions on tablets that name men of Meluhha.

    The one route to a seal tied to a person whose name is written in a readable script.

  • New and unpublished texts

    Inscriptions found or published since 2010, with photographs or reliable drawings.

    38 predictions are frozen and waiting to be scored on texts nobody here has seen.

  • Better scans of old plates

    Greyscale scans at 600 dpi or more of the 1930s excavation plates and of the published scene tablets.

    Tests on pictures stalled at about 100 dpi, where the details cannot be seen.

Tasks for epigraphists, archaeologists and Assyriologists

  • S1Confirm the shape of five ‘round’ sealsSpecialists · Anyone careful

    Why: The round-seal finding rests on 8 seals from the Indus region. Only 3 are confirmed round in a printed excavation report. The other 5 rest on one database’s type code.

    Done when: For each of Chanhu-daro C-32, M-2039, M-1369, the Dholavira seal ICIT 4247.1 and the Rakhigarhi seal ICIT 5468.1: its shape, the source that shows it (book, page, plate or figure), and whether the published drawing matches our reading of the signs.

    Start from: experiments/redteam_round_order/RESULTS.md experiments/redteam_round_format/RESULTS.md

  • S2Build short name lists for Gulf sitesSpecialists

    Why: The name-matching method only works with short lists (200 spellings or fewer) of names that people at one place could have had. No list of names from the Gulf exists.

    Done when: One CSV per place (for example Dilmun, Failaka, Magan, Susa): name, syllabic spelling, source text and date. Every name attested in a published text; no reconstructed names.

    Start from: experiments/onomasticon/RESULTS.md experiments/elamite_names/short_Elamite_core.csv

  • S9Find newly published inscribed objectsSpecialists · Anyone careful

    Why: 38 predictions were frozen before any new find was scored. Only 2 new objects are scorable so far, and each prediction needs between 2 and 30.

    Done when: New rows in experiments/new_finds/new_texts.csv, each with its citation and a confidence for every sign. Leave the scoring to the frozen scripts.

    Start from: docs/PREDICTION_REGISTRY.md experiments/new_finds/

03Check

A careful reader of photographs catches errors no test can

Every statistic rests on how each sign was read. Compare a reading with a published photograph or drawing, and report any mismatch with the error form. The same form takes any other error on the site or in the code.

  • S7Spot-check 50 links to the 1930s excavation registersAnyone careful

    Why: 1,524 texts were linked to their entries in the printed excavation registers by automatic matching. The depth and findspot tests depend on those links.

    Done when: 50 randomly drawn links checked against the scanned registers (public domain, on archive.org), each marked right, wrong or unsure, with page numbers.

    Start from: experiments/old_registers/RESULTS.md experiments/old_registers/registers.csv

04Red team

Breaking one of our results counts as much as adding one

  1. Pick a finding and name the attack: a confound, a leak between the test texts and the rest, or a weak comparison with chance.
  2. Open a test proposal with your pass and fail marks.
  3. Seal it, run it and report it, whichever way it goes. A broken result is credited like any other.

Specialist reviews are welcome too. The round-seal finding most needs one before it goes into a paper.

05Readings

Your own reading is scored the same way as every other

Five published readings have been scored here, and none beat its own sounds shuffled among the signs.

  1. Fix your key before it is scored

    Give one sound per sign, by sign number in Mahadevan 1977 or Wells. Name the language and the dictionary to score against. Nothing changes after the run.

  2. Submit it on GitHub

    Use the reading submission form. The key and its fingerprint are logged in public before any score exists.

  3. It is scored on texts it was not built from

    It must beat the same key with its sounds shuffled, and keys fitted to random sign strings.

  4. The result is published either way

    A key that passes goes to the red team. A key that fails joins the closed routes, with credit to you.

Today the bench runs by hand from experiments/bench_pierson/. Turning it into a one-command tool is starter task S5.

Everyone taking part follows the code of conduct. Writing about the project? The typeface and logo are free to download.